
Node Crashes
When using DolphinDB, the client may occasionally report the following error: Connection
refused. In this case, running the ps command on Linux shows that the
DolphinDB process is no longer running. This article explains how to identify the
various causes of this issue and provides the corresponding solutions.
1. Check Node Logs to Identify the Cause
The operating status of each DolphinDB node is recorded in its corresponding log file. Analyzing these logs provides insight into the operating status of DolphinDB and helps identify and locate errors. When a node fails, shutdowns unrelated to DolphinDB system operation typically fall into one of the following three categories:
- The node was manually shut down from the web-based cluster management interface
or stopped by calling the
stopDataNodefunction. - The node process was terminated using the operating system's kill command.
- The node shut down because the license expired.
To investigate, check whether the node logged the message “MainServer shutdown”
before it exited. The following example assumes that the failed node is
datanode1:
less datanode1.log|grep "MainServer shutdown"If the command output resembles the figure below and the estimated exit time is consistent with the incident, you can preliminarily conclude that the system initiated the shutdown.

The following content describes the additional troubleshooting steps for each scenario.
First scenario: Check the controller log (controller.log) to
determine whether the node was manually shut down from the web-based cluster
management interface or stopped by calling the stopDataNode
function. An example command is shown below:
less controller.log|grep "has gone offline"
If the log contains messages like those shown in the figure above, the node was
either manually shut down from the web interface or stopped by calling the
stopDataNode function.
Second scenario: Check the runtime log of the failed node for a "Received signal"
message to determine whether the node process was terminated using the operating
system's kill command. An example command is shown below:
less datanode1.log|grep "Received signal"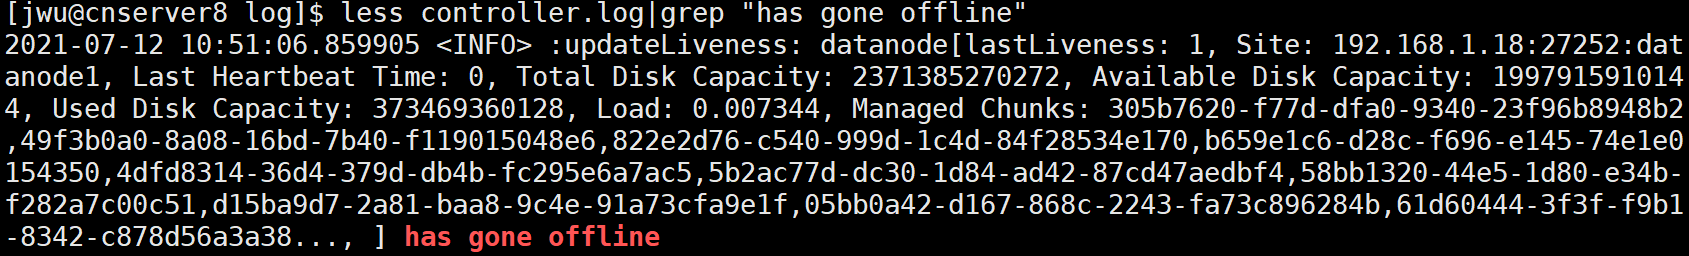
If a message like the one shown above appears at the relevant time, the process was
terminated by the kill command.
Third scenario: Check whether the node's runtime log contains the message “The
license has expired” to determine whether the node shut down because its license
expired: 
If the message shown above appears, the node exited because the license expired. Monitor the license expiration date and renew the license promptly to avoid service interruptions caused by an expired license. Starting with versions 1.30.11 and 1.20.20, DolphinDB supports updating the license online without restarting the system. Versions earlier than DolphinDB 1.30.11 and 1.20.20 do not support online license updates. After updating the license, you must restart the data nodes, controllers, and agents; otherwise, the data nodes may exit.
Note: In standalone mode, the node log is stored by default in the server directory
under the installation directory and is named dolphindb.log. In
cluster mode, logs are stored by default in the server/log directory. To change the
log file path, you must specify it with the logFile parameter on the command
line. If any nodes in the cluster are running, use the following ps
command to view the log file location for each node. The logFile parameter
specifies the path and name of the log file:
ps -ef | grep dolphindb
If the logs do not contain any of the messages described above, check the relevant operating system logs.
2. Check Operating System Logs for the OOM Killer
The Linux kernel provides a mechanism called the OOM killer (Out Of Memory killer).
It monitors processes that consume excessive memory, particularly those whose memory
usage increases sharply, and automatically terminates them to prevent the system
from running out of memory. Use the dmesg command to check whether
the OOM killer was triggered, as shown in the following example:
dmesg -T|grep dolphindb
As shown above, if the message “Out of memory:Kill process” appears, DolphinDB
consumed more memory than the operating system had available, causing the operating
system to terminate the DolphinDB process. To resolve this issue, use the
maxMemSize parameter to set the maximum amount of memory available to the
node. In standalone mode, modify dolphindb.cfg; in cluster mode,
modify cluster.cfg. Set this parameter carefully. A value that is
too low can severely limit cluster performance, while a value that is too high may
cause the operating system to terminate the process. For a machine with 16 GB of
memory and only one deployed node, a value of approximately 12 GB is
recommended.
When using the dmesg command above to display logs, a “segfault”
message like the one shown below indicates a segmentation fault. This occurs when an
application accesses memory outside the space allocated to it by the system:

Possible causes of a segmentation fault include:
- DolphinDB accesses the system data area, most commonly by operating on a pointer to address 0x00.
- Out-of-bounds memory access, such as an array index out of bounds or mismatched variable types, causes DolphinDB to access memory that does not belong to it.
- Stack overflow (the default stack size on Linux is generally 8192 KB; use the
ulimit -scommand to check it).
If core dumps are configured correctly, a corresponding core file is generated and
can be debugged using gdb.
3. Examine the Core File
If an exception terminates a program while it is running, the operating system automatically records the program's memory state at the time of termination and saves it to a specific file. This process is called a core dump. Although a core dump is often described as a memory snapshot, it contains much more than memory data. A core dump also records other critical program state, including register data such as the program pointer and stack pointer, as well as other processor and operating system state information. Core dumps are extremely useful for diagnosing and debugging programs. Some errors, such as invalid pointers, can be difficult to reproduce in a production environment. A core dump provides detailed context from the time of the failure, helping developers pinpoint the problem. By default, the core file is generated in the same directory as the executable and is named core.***, where *** is a sequence of digits.
3.1 Core File Configuration
3.1.1 Control Core File Generation
First, enter ulimit -c in the terminal to check whether core
file generation is enabled. A result of 0 indicates that this feature is
disabled and no core file will be generated. A positive numeric value or
“unlimited” indicates that core file generation is enabled.
Because core files can be large, setting the value to “unlimited” is
recommended so that the core file size is not restricted. Use the following
command to configure this setting:
ulimit -c unlimitedThis configuration applies only to the current session and must be configured again after you log in again. Use either of the following methods to make the configuration permanent:
- Add the line
ulimit -S -c unlimited >/dev/null
                                2>&1
to /etc/profile, save the file, and restart the server. Alternatively, without restarting the server, runsource /etc/profileto apply the configuration immediately. /etc/profile applies to all users. To apply the setting to only one user, modify that user's ~/.bashrc or ~/.bash_profile file. - Add the following two lines to the end of /etc/security/limits.conf to enable core dumps for all users:
# Enable coredump with unlimited file-size for all users
*		soft	core		unlimited
root		soft	 core		unlimited
Note: Because DolphinDB data nodes are started by the agent, core dump generation does not take effect until the agent is restarted. After enabling core dump generation, restart the agent and then restart the data nodes.
3.1.2 Change the Core File Storage Path
By default, a core file is named core.pid, where pid is the process ID of the program that encountered the segmentation fault. By default, the core file is saved in the program's current directory.
/proc/sys/kernel/core_uses_pid controls whether the process ID is appended to the generated core file name. Set it to 1 to append the process ID or 0 to omit it. Use the following command to change this setting:
echo "1" > /proc/sys/kernel/core_uses_pid/proc/sys/kernel/core_pattern specifies the storage location and file name of core files. However, the configured storage path may be reset after the machine restarts. To make the setting persistent, add kernel.core_pattern=/data/core/core-%e-%p-%t.core to /etc/sysctl.conf. Use the following command to save core files in the /corefile directory and name them in the format core-command-name-pid-timestamp:
echo /corefile/core-%e-%p-%t > /proc/sys/kernel/core_pattern The parameters used in the preceding command are as follows:
- %p: Insert the process ID into the file name.
- %u: Insert the current user ID into the file name.
- %g: Insert the current group ID into the file name.
- %s: Insert the signal that caused the core dump into the file name.
- %t: Insert the UNIX timestamp when the core dump occurred into the file name.
- %h: Insert the host name of the machine where the core dump occurred into the file name.
- %e: Insert the name of the executable that generated the core dump into the file name.
In most cases, you can use the default parameter settings. You can change the core file path and name to suit your environment.
Note:
-
Before configuring the core file storage path, create the directory and ensure that the user running the process has read and write permissions for it. Otherwise, core files cannot be generated. We recommend setting the directory permissions to 777.
chmod 777 /path2/corefile -
Monitor the free space on the disk to ensure that core files do not interfere with the storage of DolphinDB metadata and partition data.
3.1.3 Test Core File Generation
Use the following command to send a SIGSEGV signal to a process and terminate
it. In this example, the process ID obtained using ps is
24758:
kill -s SIGSEGV 24758If a core file is generated in the core file directory, the configuration is valid.
3.2 Debug Core Files with gdb
If gdb is not installed, install it first. For example, use the following command to install gdb on CentOS:
yum install gdbUse the following syntax to debug a core file: gdb [exec file] [core
file]. Then run bt to view the stack trace:

3.3 Conditions That Prevent Core File Generation
In Linux, signals provide a mechanism for handling asynchronous events. Each signal has a default action. Click here for the signals provided by Linux and their default actions. The main default actions include ignoring the signal (Ignore), suspending the process (Stop), terminating the process (Terminate), and terminating the process while generating a core dump. If all signals use their default actions, the following signals generate a core dump:
| Signal | Action | Comment |
|---|---|---|
| SIGQUIT | core | Quit from keyboard |
| SIGILL | core | Illegal Instruction |
| SIGABRT | core | Abort signal from abort |
| SIGSEGV | core | Invalid memory reference |
| SIGTRAP | core | Trace/breakpoint trap |
Linux provides additional signals beyond those listed above. Some signals do not generate a core dump. For example:
(1) Neither suspending a process with Ctrl+z nor terminating it
with Ctrl+C generates a core dump. The former sends the
SIGTSTP signal, whose default action is to suspend the process (Stop
Process). The latter sends the SIGINT signal, whose default action is to
terminate the process (Terminate Process).
(2) The kill -9 command sends the SIGKILL signal, whose
default action is to terminate the process without generating a core file.
(3) Check the corresponding DolphinDB log. If it contains “Received signal 15,” as shown below, the DolphinDB process was terminated by SIGTERM, the default signal sent by the kill command. No core file is generated.

A core file is also not generated under the following conditions:
(a) The process has a set-user-ID, but the current user does not own the program file.
(b) The process has a set-group-ID, but the current user does not belong to the group that owns the program file.
(c) The user does not have write permission for the current working directory.
(d) The core file is too large.
4. Prevent Node Failures
In enterprise production environments, DolphinDB often serves as both a streaming data hub and a historical data warehouse, providing data queries and computations for business users. When many users access the system, improper usage can easily cause the server to crash. Follow these recommendations to minimize the risk of improper usage.
4.1 Avoid Infinite Recursion
A user-defined recursive function without a termination condition results in infinite recursion. Each recursive call consumes stack space. When the stack is exhausted, a stack overflow occurs and eventually terminates the process.
For example, calling the following recursive function causes the node to crash. Avoid similar function definitions.
def danger(x){
  return danger(x)+1
}

danger(1)
4.2 Monitor Memory Usage and Avoid Sustained High Memory Utilization
Sustained high memory utilization can easily result in an out-of-memory (OOM) error. For information about monitoring and efficiently using memory, see the sections on configuring write cache for a DFS database and streaming message cache queues in Memory Management.
4.3 Avoid Concurrent Multithreaded Access to Certain In-Memory Tables
The DolphinDB built-in programming language imposes rules on table operations and access. For example, some in-memory tables do not support concurrent writes. Failure to follow these rules can cause the server to crash. The following example creates a regular in-memory table partitioned by RANGE on the id field:
t=table(1:0,`id`val,[INT,INT])
db=database("",RANGE,1 101 201 301)
pt=db.createPartitionedTable(t,`pt,`id)
The following code starts two write jobs that write to the same partition. Running the code causes the server to crash.
def writeData(mutable t,id,batchSize,n){
	for(i in 1..n){
		idv=take(id,batchSize)
		valv=rand(100,batchSize)
		tmp=table(idv,valv)
		t.append!(tmp)
	}
}

job1=submitJob("write1","",writeData,pt,1..300,1000,1000)
job2=submitJob("write2","",writeData,pt,1..300,1000,1000)
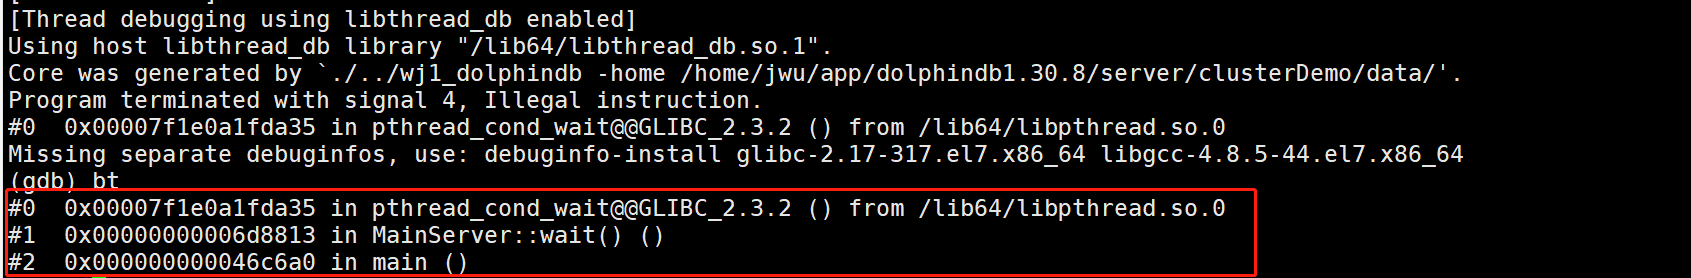
The generated core file is shown below:
4.4 Catch Exceptions in User-Defined Plugins
DolphinDB allows you to develop user-defined plugins to extend system functionality. Plugins run in the same process as the DolphinDB server. If a plugin crashes, the entire server crashes. Therefore, ensure that your plugins implement robust error detection. Only the thread that executes a plugin function may throw exceptions, because the server catches exceptions when invoking the function. All other threads must catch and handle their own exceptions rather than throw them. For details, see DolphinDB Plugin.
5. Summary
The DolphinDB DFS database has a complex architecture, and node failures can occur for many different reasons. If a node fails, troubleshoot the issue by following these steps:
- Determine whether the system exited intentionally. For example, check whether the node was manually shut down through the web-based cluster management interface, stopped by calling the stopDataNode function, terminated with the kill command, or shut down because the license expired. If the database stopped for any of these reasons, the system log will contain the relevant information. Check whether a corresponding operation occurred at the time of the failure.
- Determine whether the operating system terminated the process because it ran out of memory. Check the operating system logs for OOM killer events.
- Check for improperly used scripts, such as scripts that concurrently access an unshared partitioned table from multiple threads, and for plugins that fail to catch certain exceptions.
- Inspect the core file and use gdb to obtain the stack trace. If you determine that the issue is caused by the system, save the node logs, operating system logs, and core file, and contact a DolphinDB engineer promptly.